Technical Innovations
Batch Execution Optimization
Reduced API overhead by 99% through circuit batching. Submitted 100 circuits per job instead of individual executions, enabling full training within credit constraints.
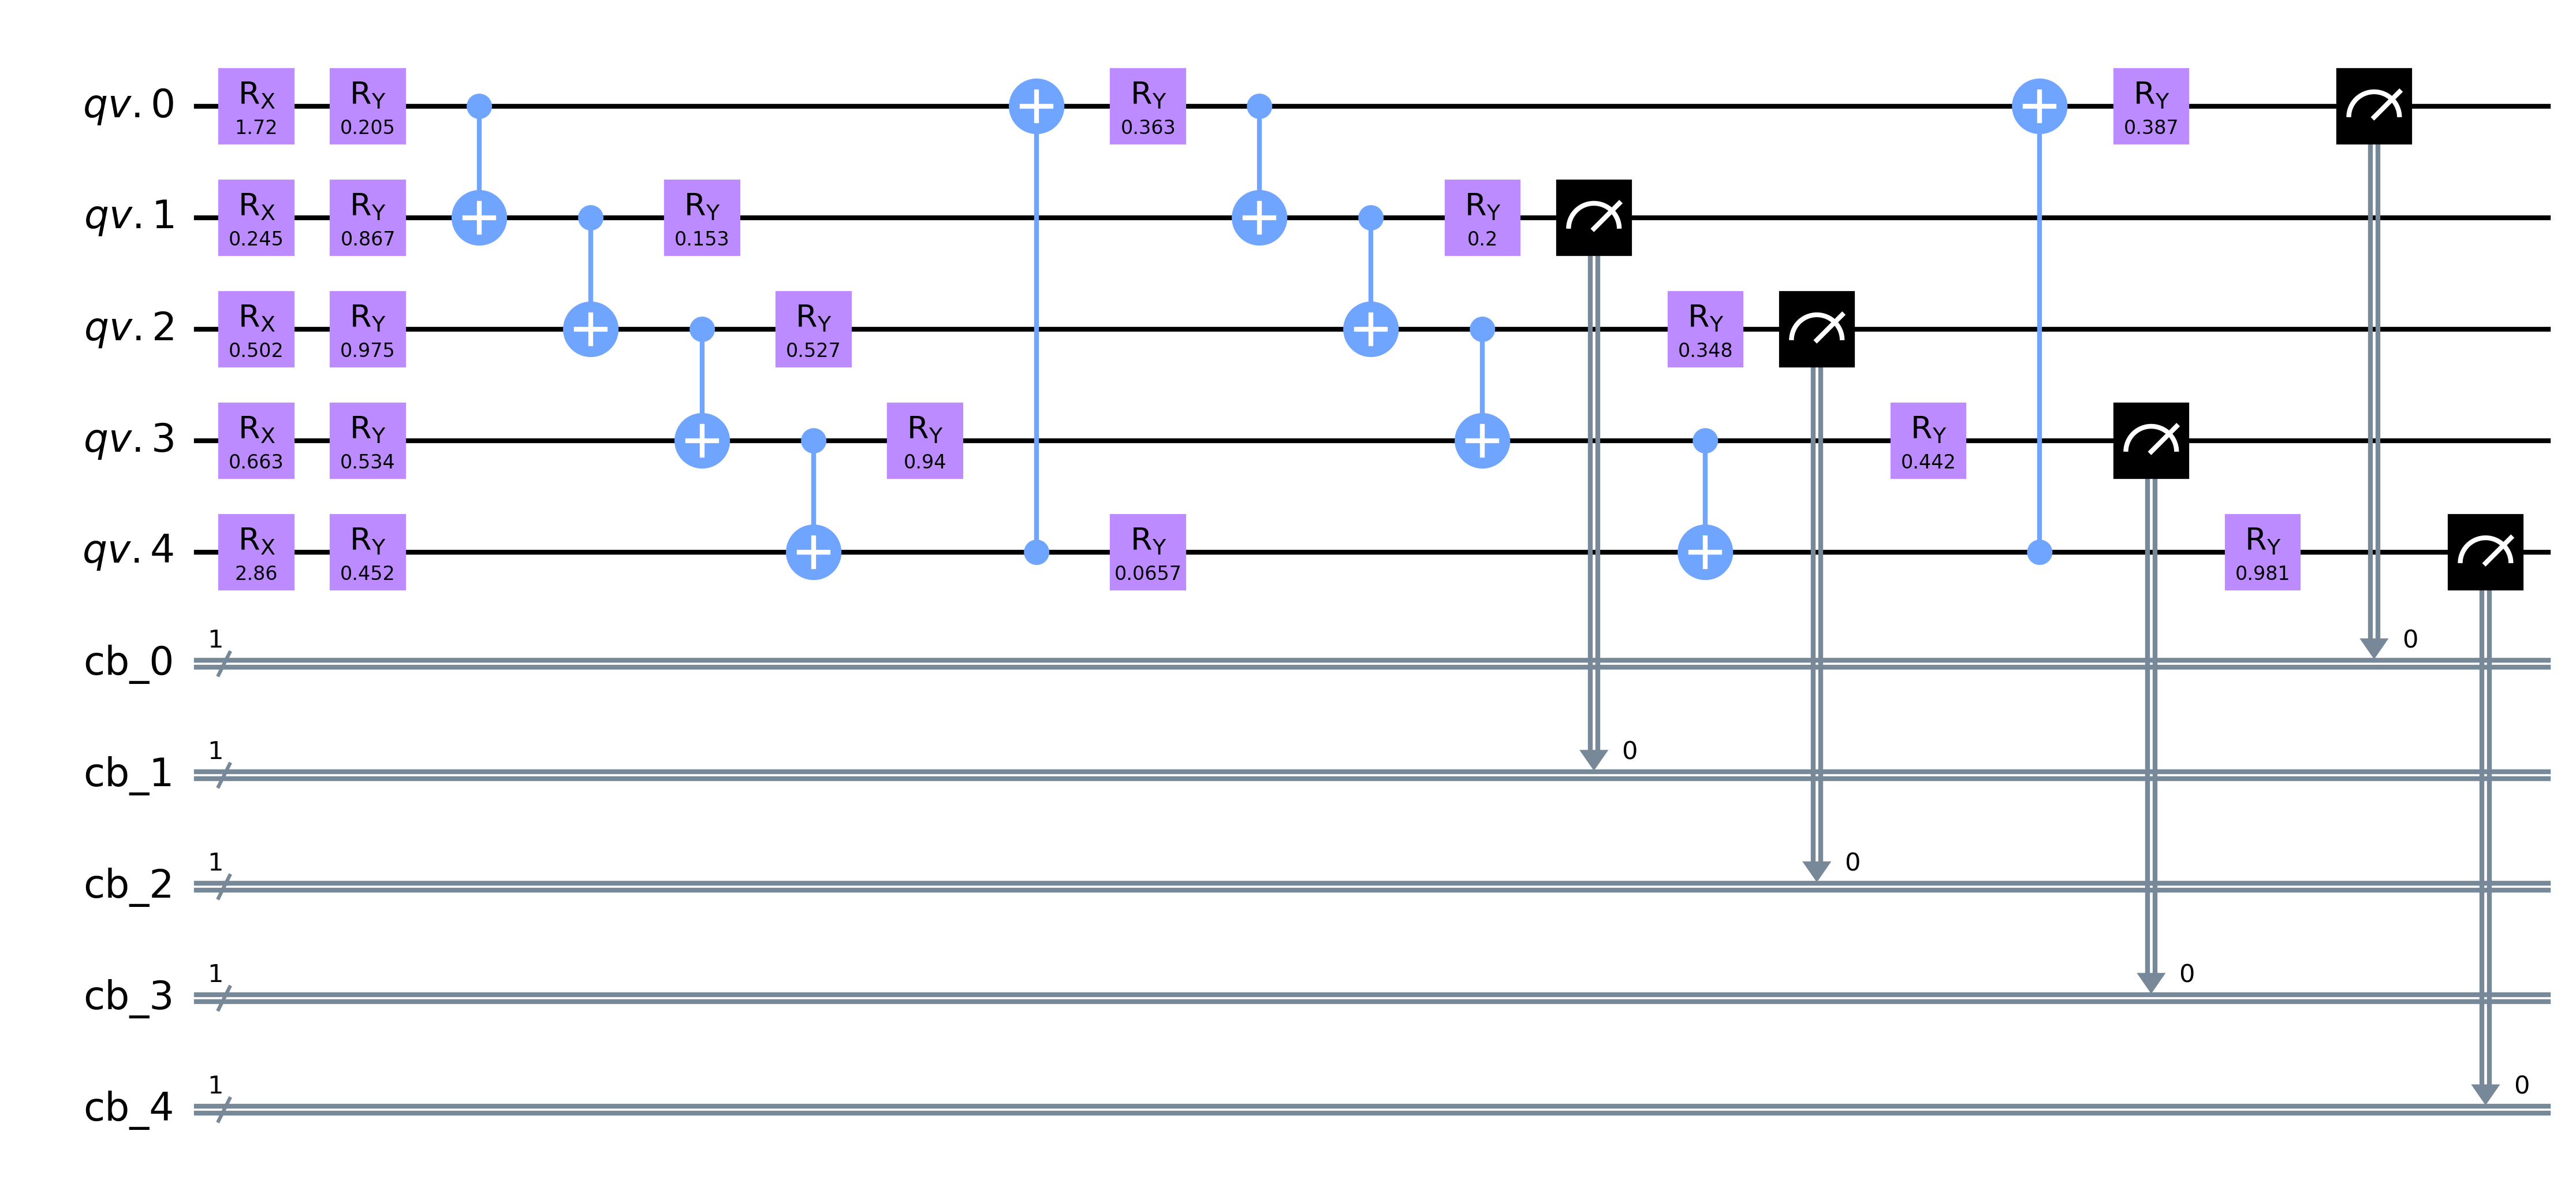
Topology-Aware Transpilation
Dynamically extracted IQM Garnet's coupling map and applied optimization level 3 to insert SWAP gates automatically, ensuring circuit validity on real hardware.
Physics-Informed Preprocessing
Implemented 0-to-π Scaling strategies to maximize Angle Embedding expressivity on the Bloch sphere, preventing phase redundancy and "feature crowding".
Class Imbalance Mitigation
Integrated a Weighted MSE cost function (Track B) to penalize minority class errors, ensuring the model doesn't just predict "safe" non-defaults.
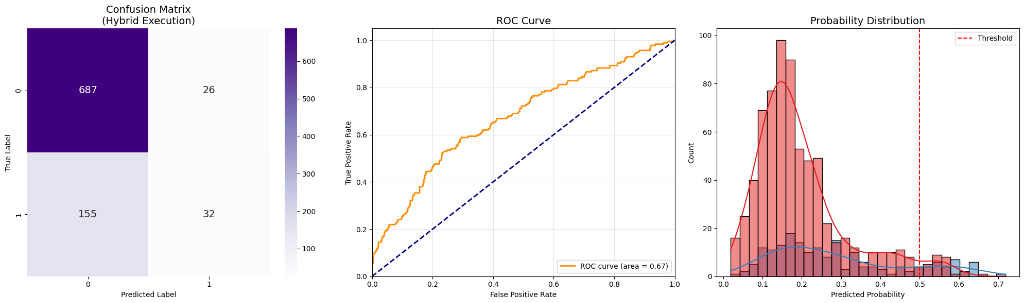
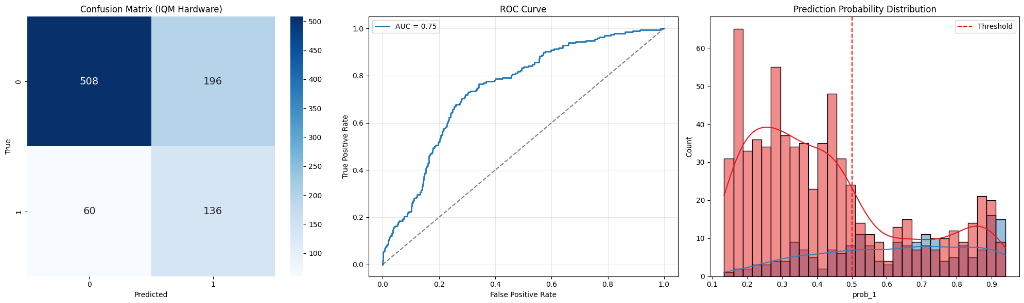
Left: Unweighted (High Accuracy, Low Recall). Right: Weighted (Balanced, High Recall).